
HY4 Flash has a promising but narrow evidence profile: Plotly reports 39/43 on one run of its DataAnalyticsBench, at $0.13 and a median 29 seconds per question. It missed four questions, including three hidden-pattern items. Tencent's internal results add broader office-task evidence, but are vendor tests. No test in this article was run by its author or in Tabbit.
The useful question is not “is HY4 Flash good?” but which task can tolerate its documented misses at its low listed rate. Tencent recommends Flash for everyday work and the larger HY4 for long-horizon software engineering. See the HY4 Flash pricing guide for rate details and HY4 Flash vs HY4 for a same-harness comparison.
Key takeaways
Plotly's one run scored 39/43; its private dataset and single sample limit generalization.
The four misses included three hidden patterns and one statistical trap.
Tencent's 85-user, 259-task WorkBuddy blind test is useful vendor evidence, not independent replication.
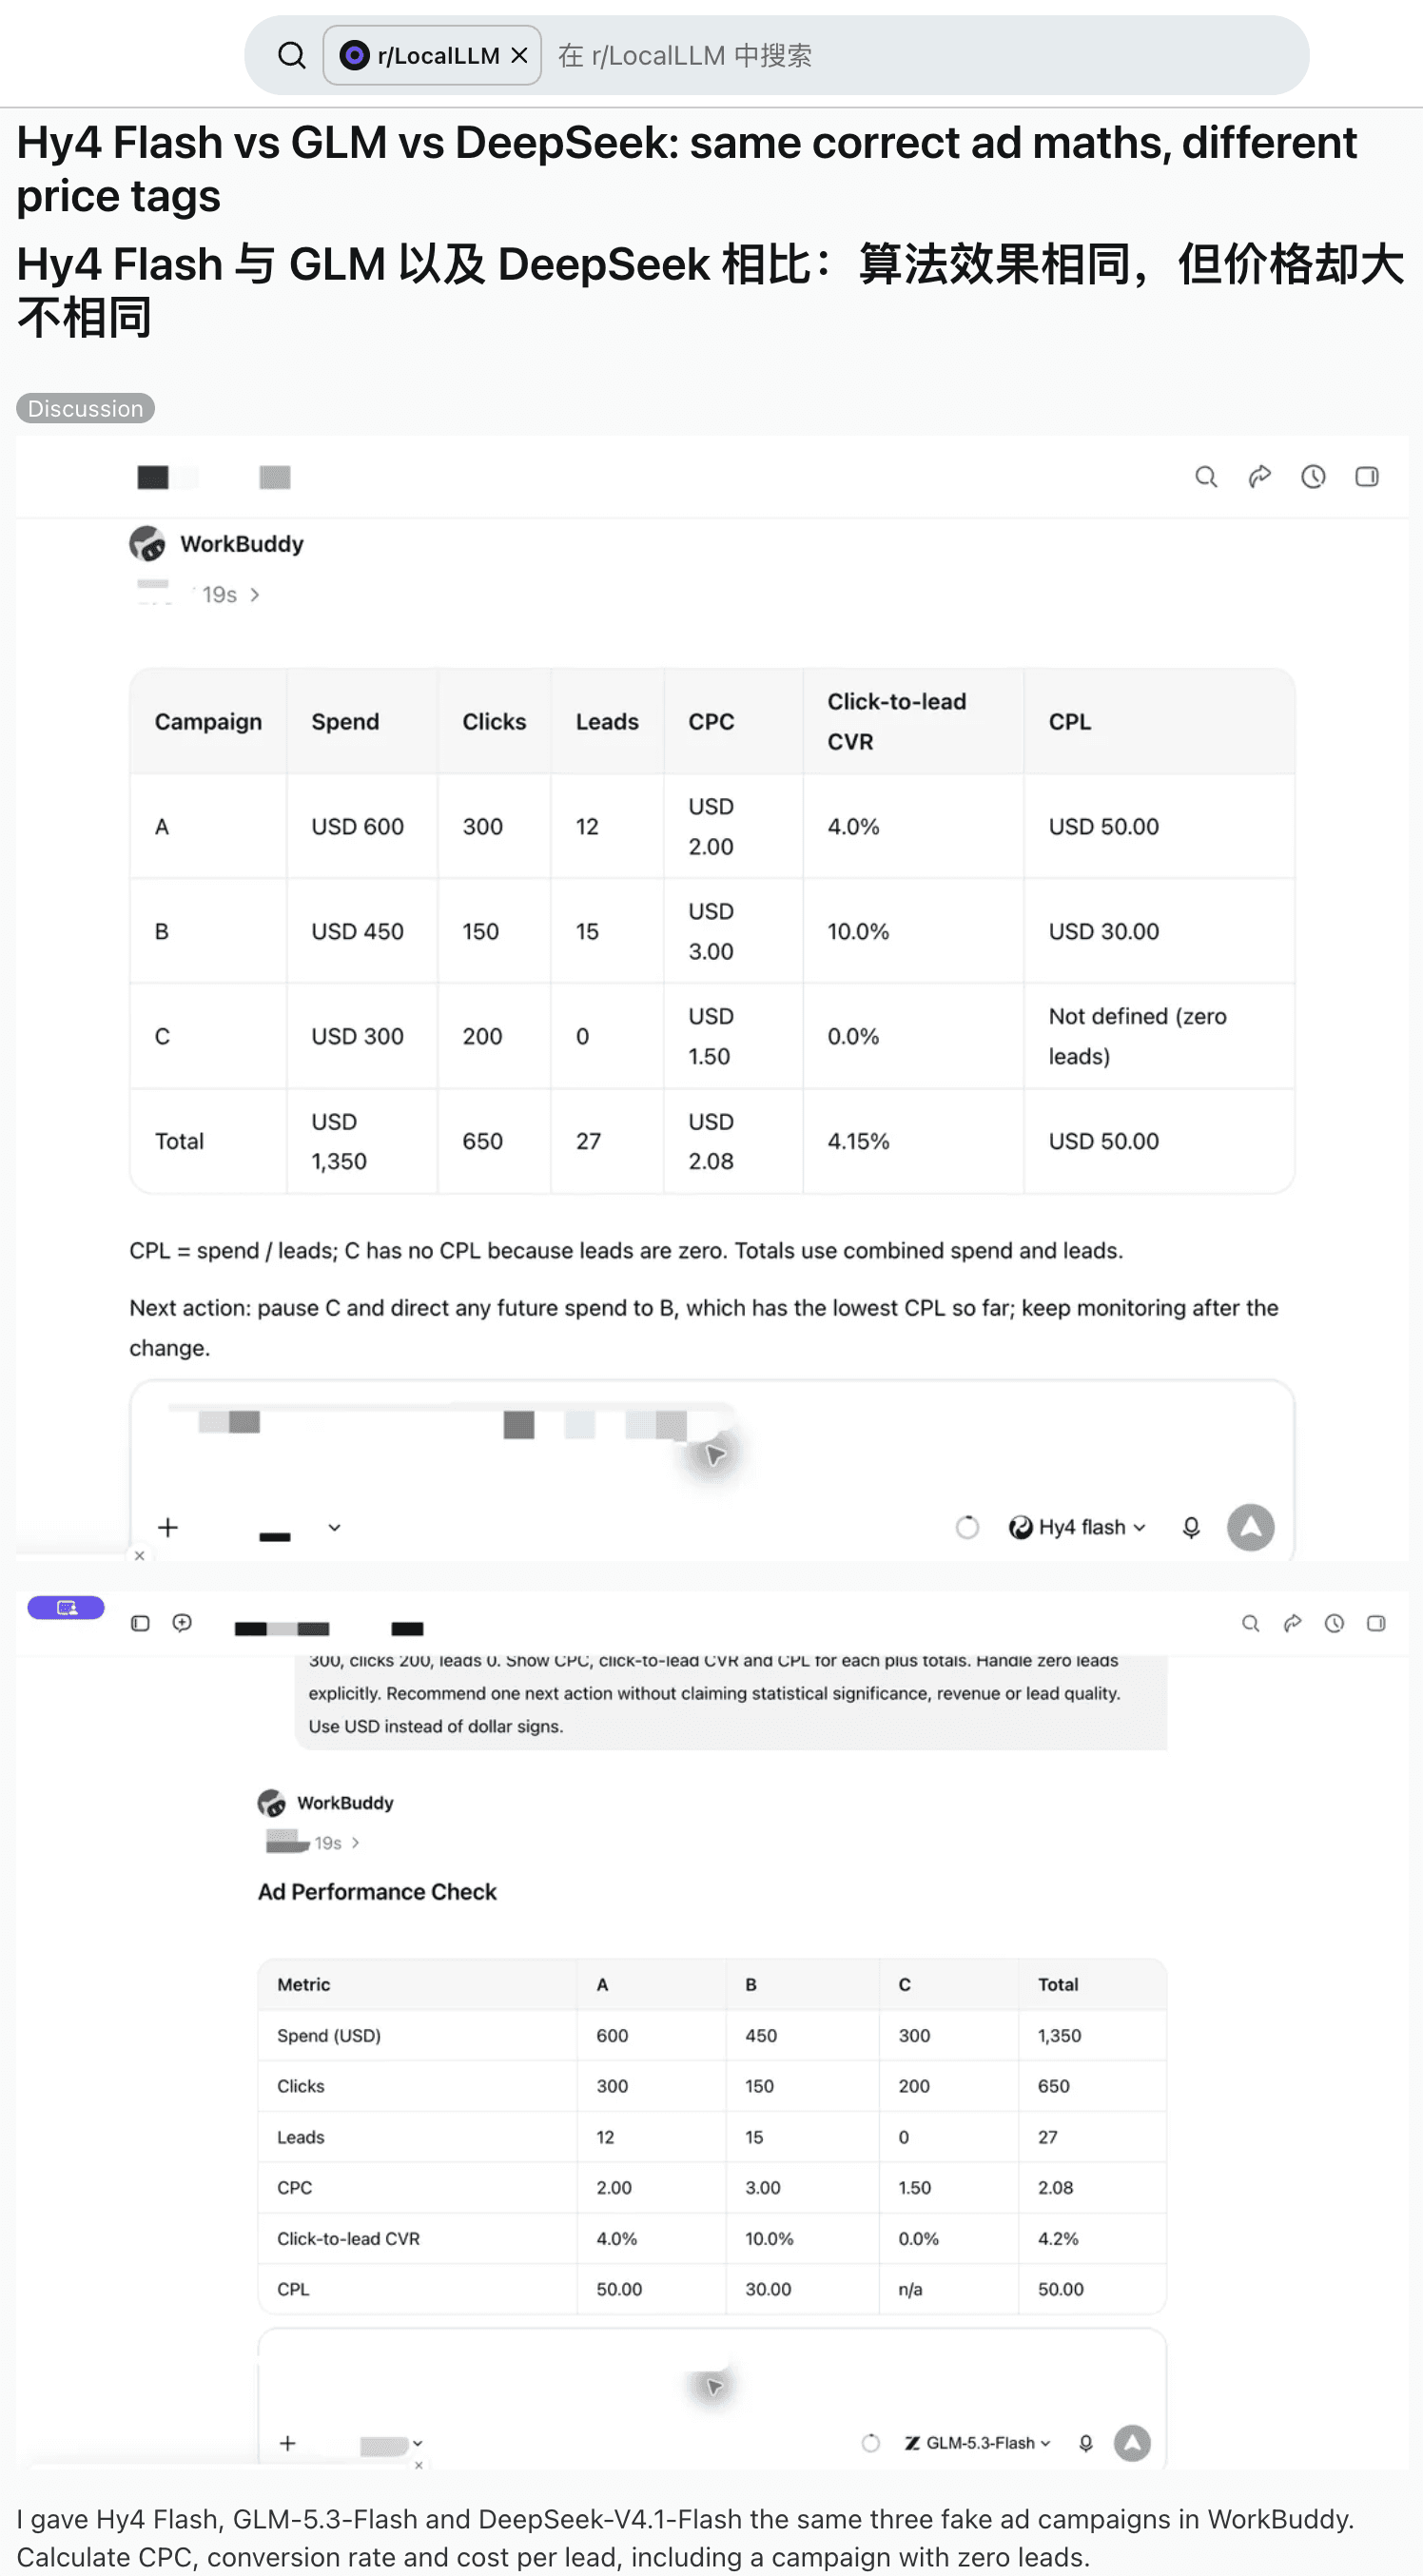
A Reddit same-task report found all models correct on simple arithmetic, but DeepSeek was faster in that one run.
Test against a fixed acceptance check before moving important work to any model.
HY4 Flash evidence at a glance
| Evidence | Result | What it supports | Main limit |
|---|---|---|---|
| Plotly DataAnalyticsBench | 39/43; $0.13; 29 sec median/question | One multi-turn data-analysis setup | Private questions; one run |
| Tencent WorkIndex | Broad office-task result; task cost stated as 1/8 of DeepSeek 1017 under Max/peak pricing | Tencent's intended everyday-work use | Internal evaluation and vendor methodology |
| Tencent WorkBuddy blind test | 85 users, 259 tasks, 27 categories; satisfaction close to Claude Haiku 5.5 | Product-specific preference snapshot | No variance or independent replication in release article |
| Reddit ad-math task | Three models reportedly got totals right; DeepSeek 7 sec vs 19 sec | A narrow personal comparison | One run; no token usage or raw logs |
Plotly says it used the same harness and scoring method across models. The benchmark is a private synthetic wind-farm dataset, and each model ran once. Hy4 scored 42/43 at $2.11 and 117 seconds per question. The results suggest a cost/quality tradeoff in that specific test; they do not show that HY4 Flash is always four times faster or sixteen times cheaper.
What the misses tell us
Plotly checked its four misses manually against its answer key. Three were hidden-pattern questions where the model needed to find an unannounced issue in the data; another was a statistical threshold question. That profile matters for analytic work: correct calculations on ordinary rows do not guarantee that a model will surface an unexpected signal.
The article reports about eight calls and 4,800 output tokens per question, with 88% of inputs served from cache. Its $0.13 run cost therefore depends on the benchmark's harness, caching, and provider rates. Do not use it as a general price per report.
Where the current evidence points
| Workload | Evidence-based starting point | Check before relying on it |
|---|---|---|
| Routine calculations or document extraction | Candidate for a bounded trial | Reconcile outputs against a fixture |
| Ambiguous question handling | Plotly reported 5/5 in its test | Repeat with your own data |
| Hidden patterns or unusual anomalies | Caution: Plotly reported 2/5 | Use a second pass or another model |
| Long-horizon software engineering | Tencent recommends HY4 | Validate the full tool loop and final artifacts |
| High-volume agent calls | Low TokenHub rates may help | Compare actual usage, retries, and successful tasks |
Tencent reports decoding above 150 tokens/second and says its WorkIndex task cost is one-eighth of DeepSeek V4.1 Flash 1017 with Max reasoning and peak pricing. Those figures are claims about Tencent's selected evaluation. The independent Plotly report is more useful for a reproducible outline, although its full question set remains private.
What people asked during launch week
One Reddit user asked whether HY4 Flash “does it pick the right tool or just guess.” That is a question, not a measured failure, but it identifies a gap that benchmark totals do not automatically close. Another participant asked where the open weights were; Tencent's release page says they are planned, not that a local package is already available. Read the discussion.
In a separate WorkBuddy arithmetic comparison, the author reported: “DeepSeek finished in 7s. Hy4 and GLM both showed 19s.” All three reportedly got the arithmetic right. The post does not include token usage or raw outputs, so it supports only a narrow, self-reported comparison. Original Reddit post.
Verdict: test it on bounded tasks first
HY4 Flash is worth a controlled trial when the job is repetitive, the expected output is easy to check, and the lower TokenHub rate matters. Plotly's hidden-pattern misses are a reason to add a verification step for open-ended analysis. For a direct cost comparison, read HY4 Flash vs DeepSeek V4.1 Flash; for rates, see the pricing page.
The model is a provider route, not browser access by itself. See the HY4 Flash model resources, Tencent Hy4 browser workflow, and the DeepSeek V4.1 Flash browser workflow. A separate DeepSeek Harness guide, Feishu Base example, Tabbit CLI guide, and first-task checklist describe different model/browser routes.
Tabbit Browser offers Hy4 Flash. Download Tabbit, then select Hy4 Flash from the model list in Chat to start using it.
 Tabbit Browser

FAQ
How good is HY4 Flash in independent testing?
Plotly reports 39 of 43 on one run of its private DataAnalyticsBench, at $0.13 and a median 29 seconds per question. This is one benchmark and one sample, not a general success rate.
Is HY4 Flash better than HY4?
Not on Plotly's single DataAnalyticsBench run: HY4 scored 42 of 43 and HY4 Flash scored 39. Flash cost less and answered faster in that test. The result does not predict every workload.
Is HY4 Flash open source now?
Tencent's November 16 announcement says it plans to open-source HY4 Flash but gives no release date. Check for published weights and a license before planning local deployment.
Does the benchmark prove strong tool calling?
Plotly tested a multi-turn analytics agent using tool calls, but its private test cannot establish tool-selection reliability across other clients or workflows. The available launch-week Reddit thread includes a user asking specifically about tool-loop behavior.
Can I use HY4 Flash in Tabbit?
Tabbit Browser offers Hy4 Flash. Download Tabbit, then select Hy4 Flash from the model list in Chat to start using it.